Models
We develop DNA language models for plant genomes — from large-scale foundation models to tailored model suites. This page collects the lab’s model zoo. All model weights are openly available on Hugging Face and ModelScope.
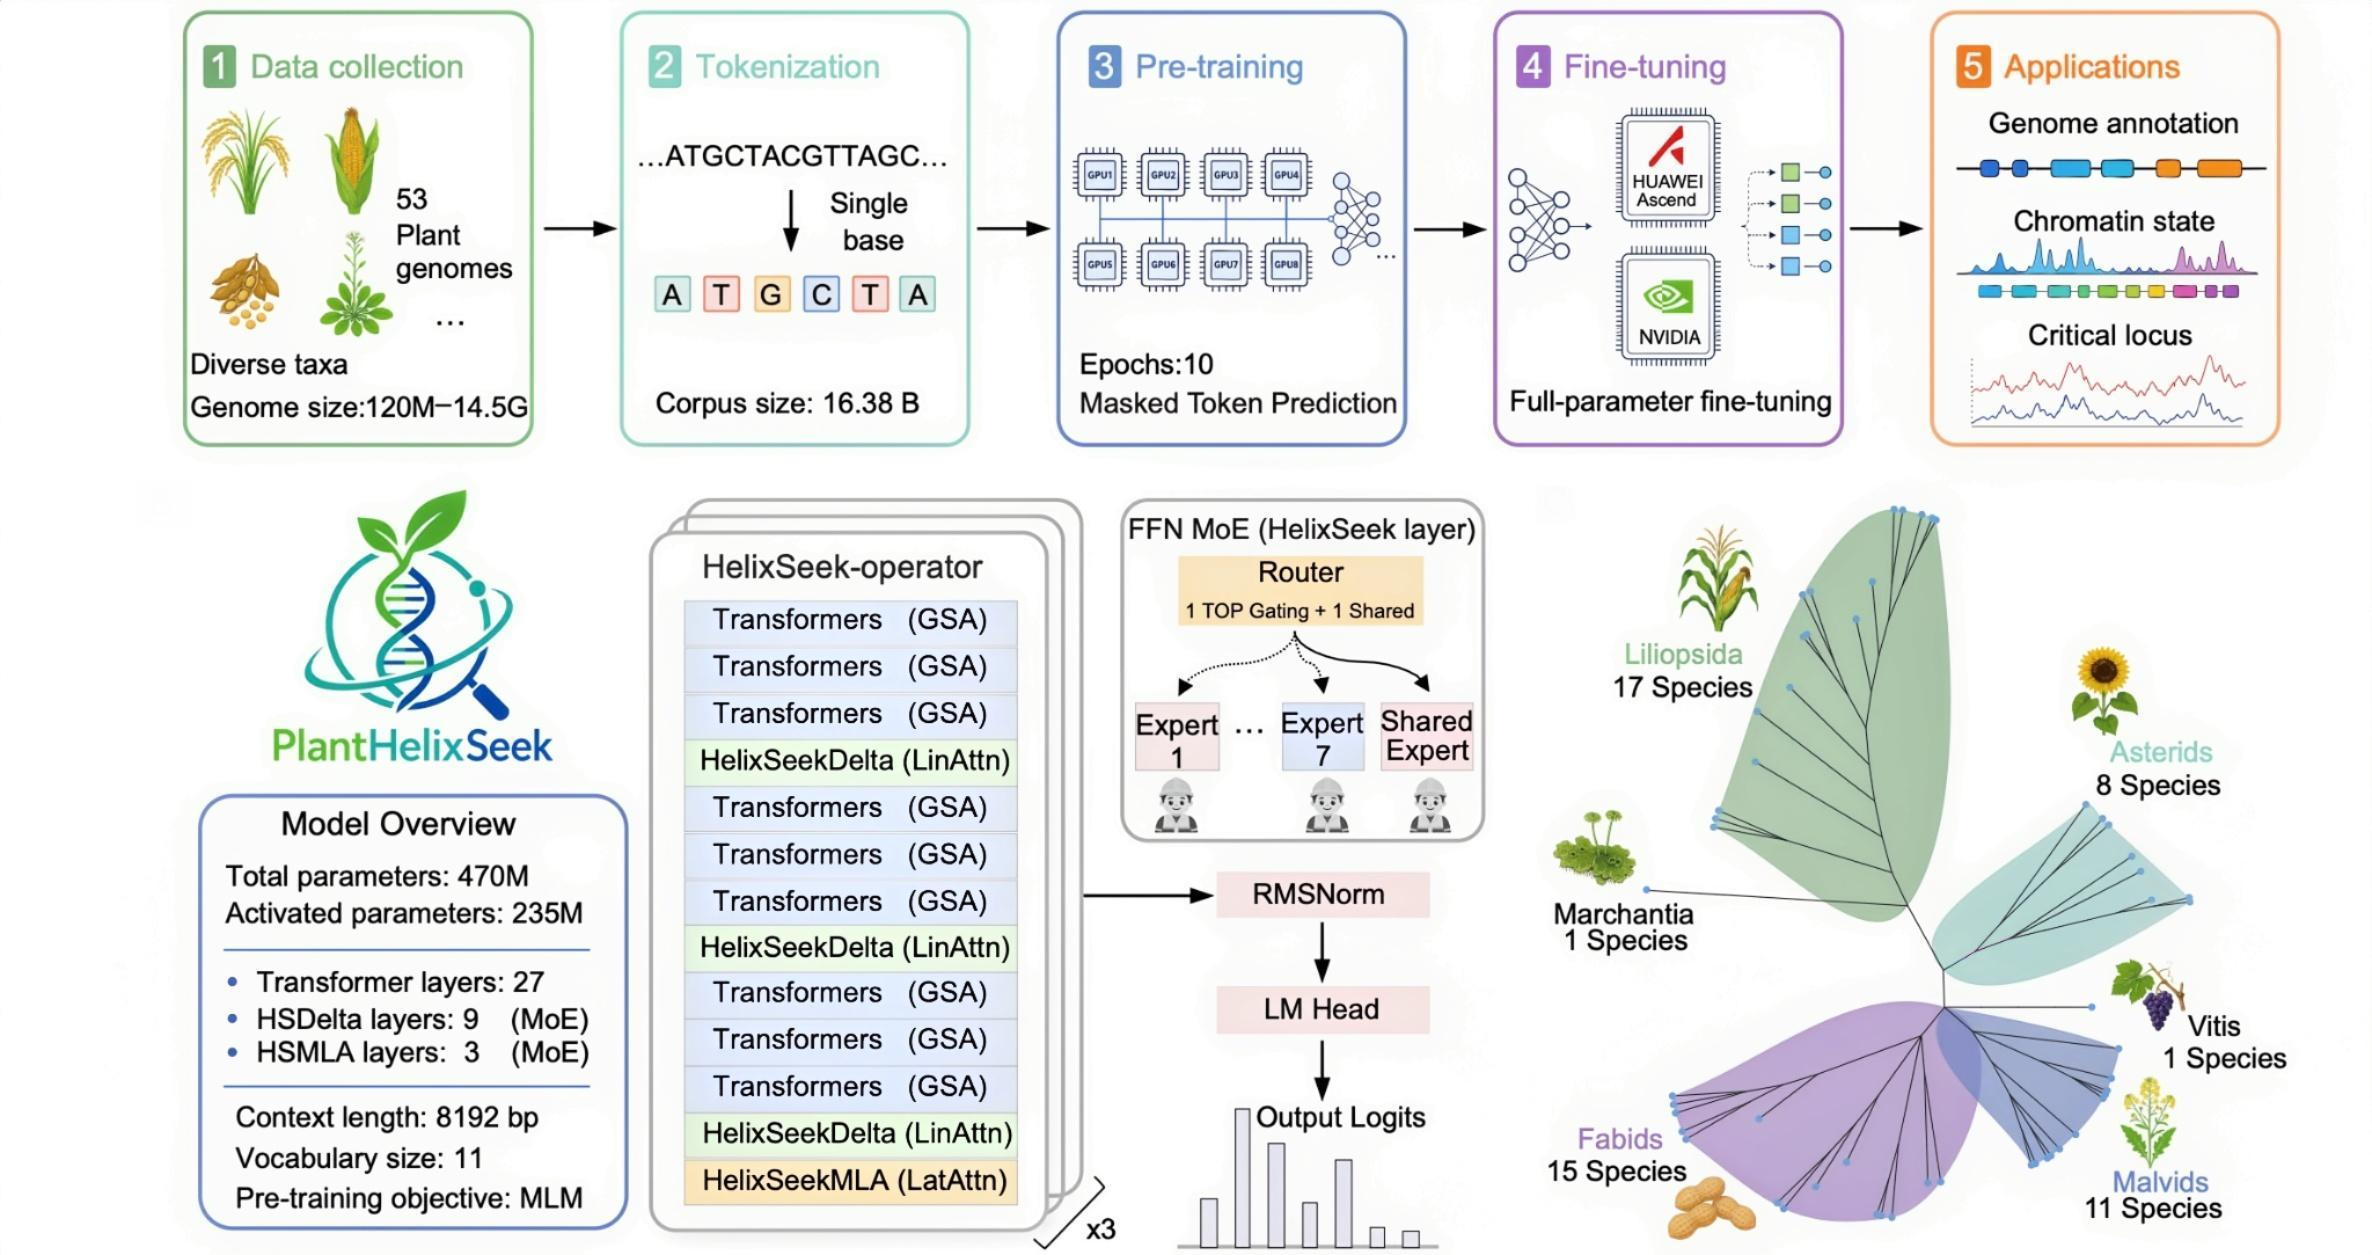
PlantHelixSeek
A plant DNA foundation model pretrained with bidirectional masked language modeling at single-nucleotide resolution, combining interleaved attention, Delta linear-attention, and MLA layers with a sparse Mixture-of-Experts feed-forward network.
params: 470M total / ~240M active
context: 8,192 bp
tokenizer: 1 nucleotide = 1 token
zoo: 1 base + 11 fine-tuned + 2 validation models
Tasks: promoter & terminator strength, lncRNA, open chromatin, conservation, H3K27ac/H3K27me3/H3K4me3, translation on/off, gene structure (BILOU), cis-regulatory elements
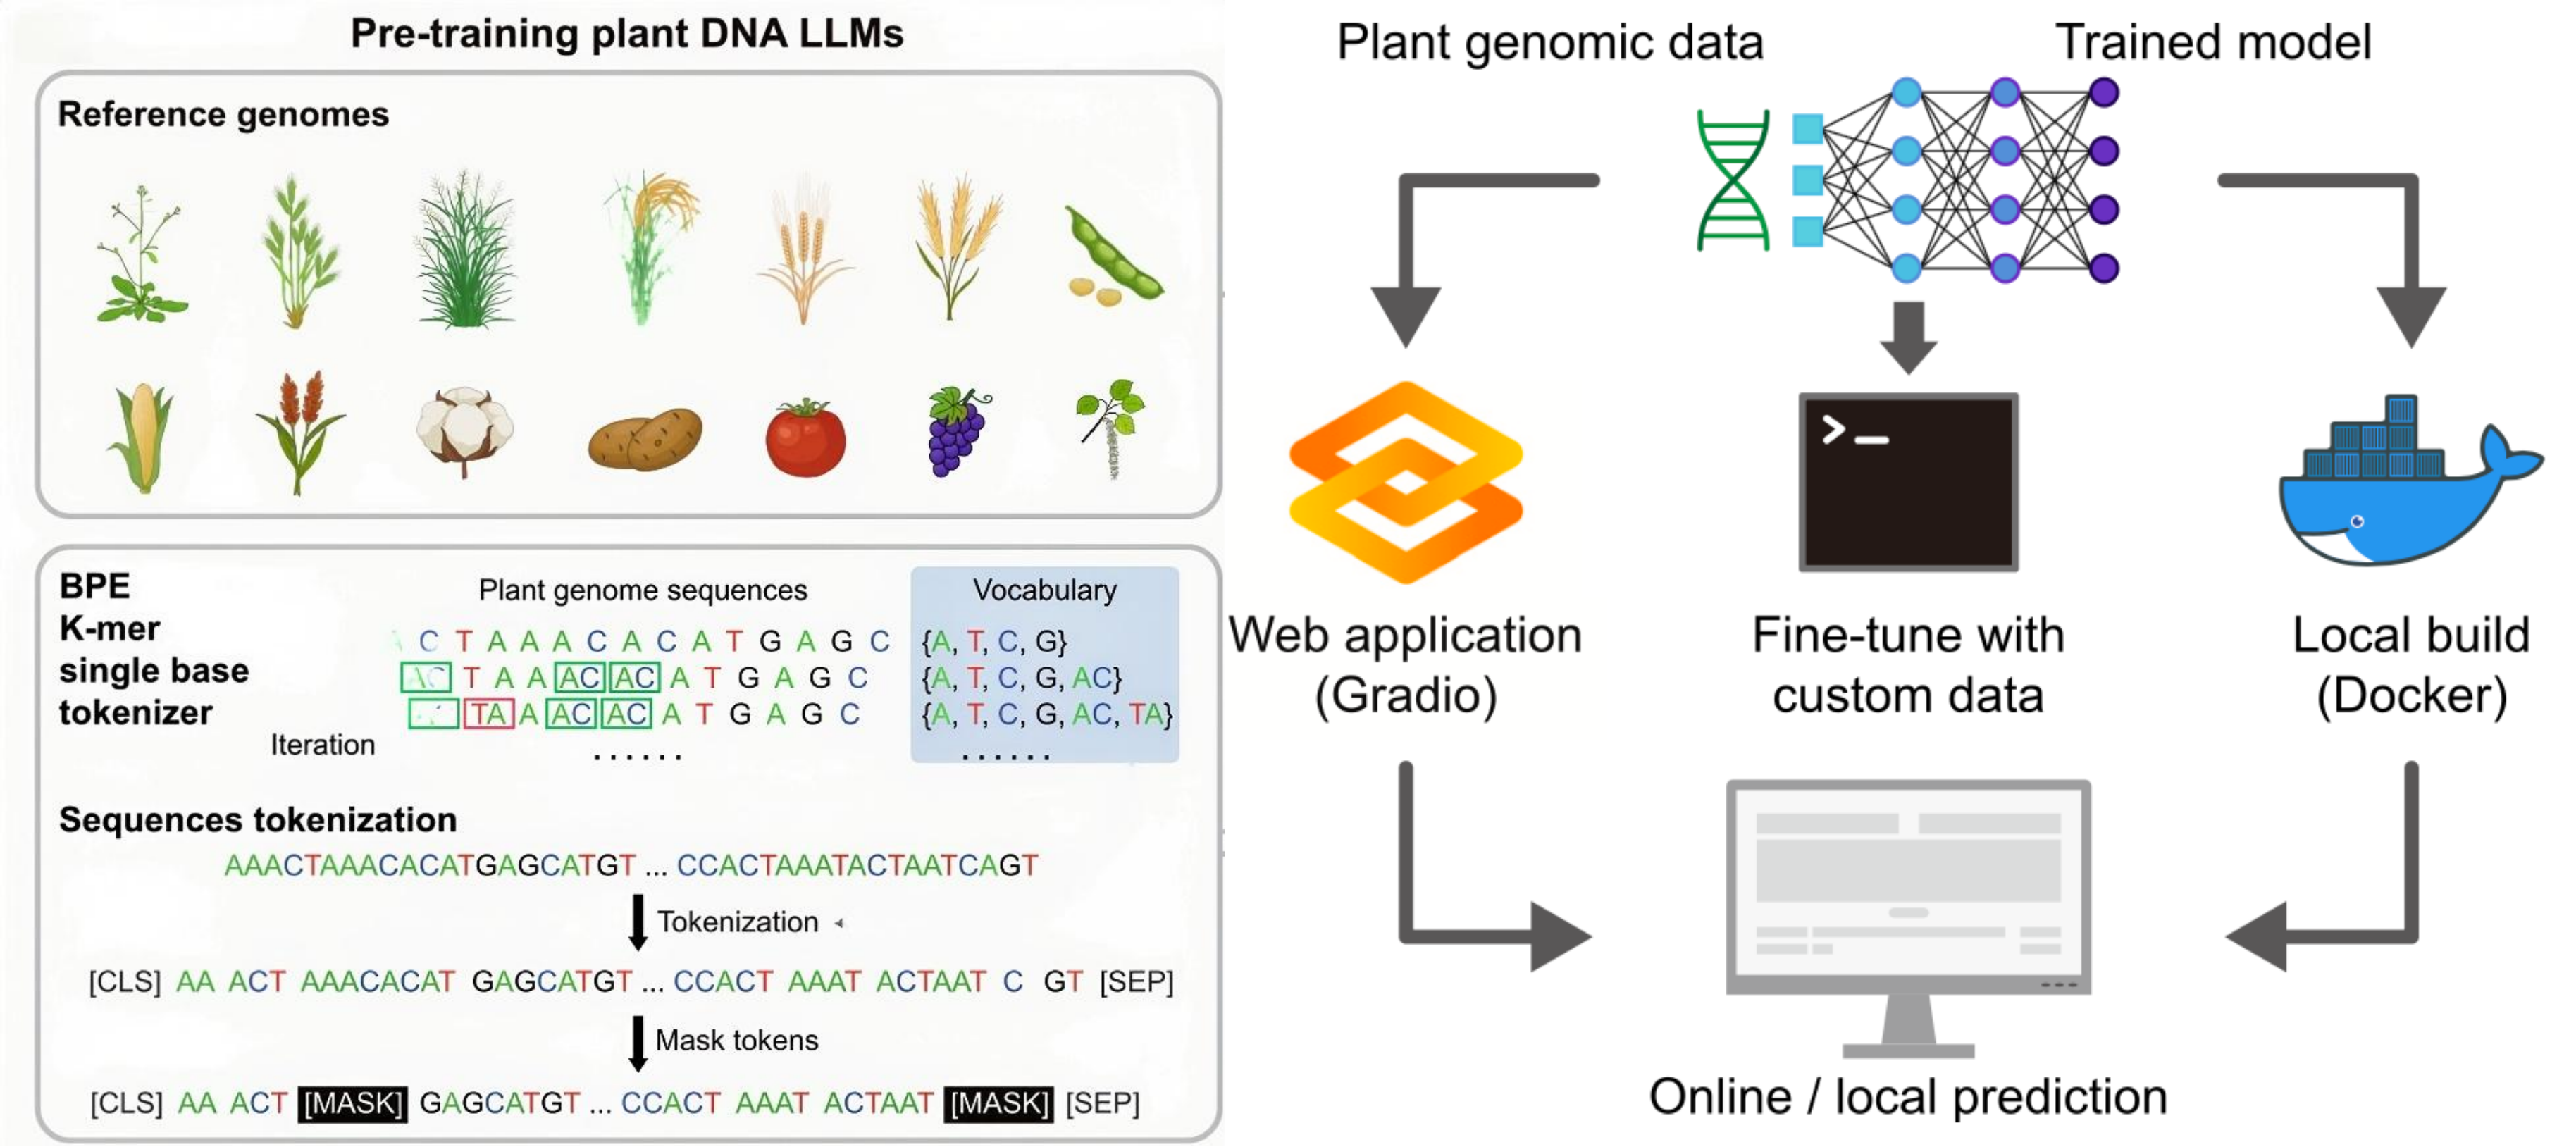
More models: Plant DNAGemma · Plant DNAGPT · Plant DNAMamba · CrossDNA — see the DNALLM documentation for details.
All models are accessible through the unified dnallm toolkit — install with pip install dnallm — see DNALLM on GitHub and the documentation.